Views are a distribution outcome, an attention threshold and sometimes a promotion artifact. They are not a complete measure of whether a video held attention. In a study of 5.3 million YouTube videos published across two months in 2016, Siqi Wu, Marian-Andrei Rizoiu and Lexing Xie examined watch-time and average-percentage-watched measures, then proposed relative engagement calibrated against video properties.
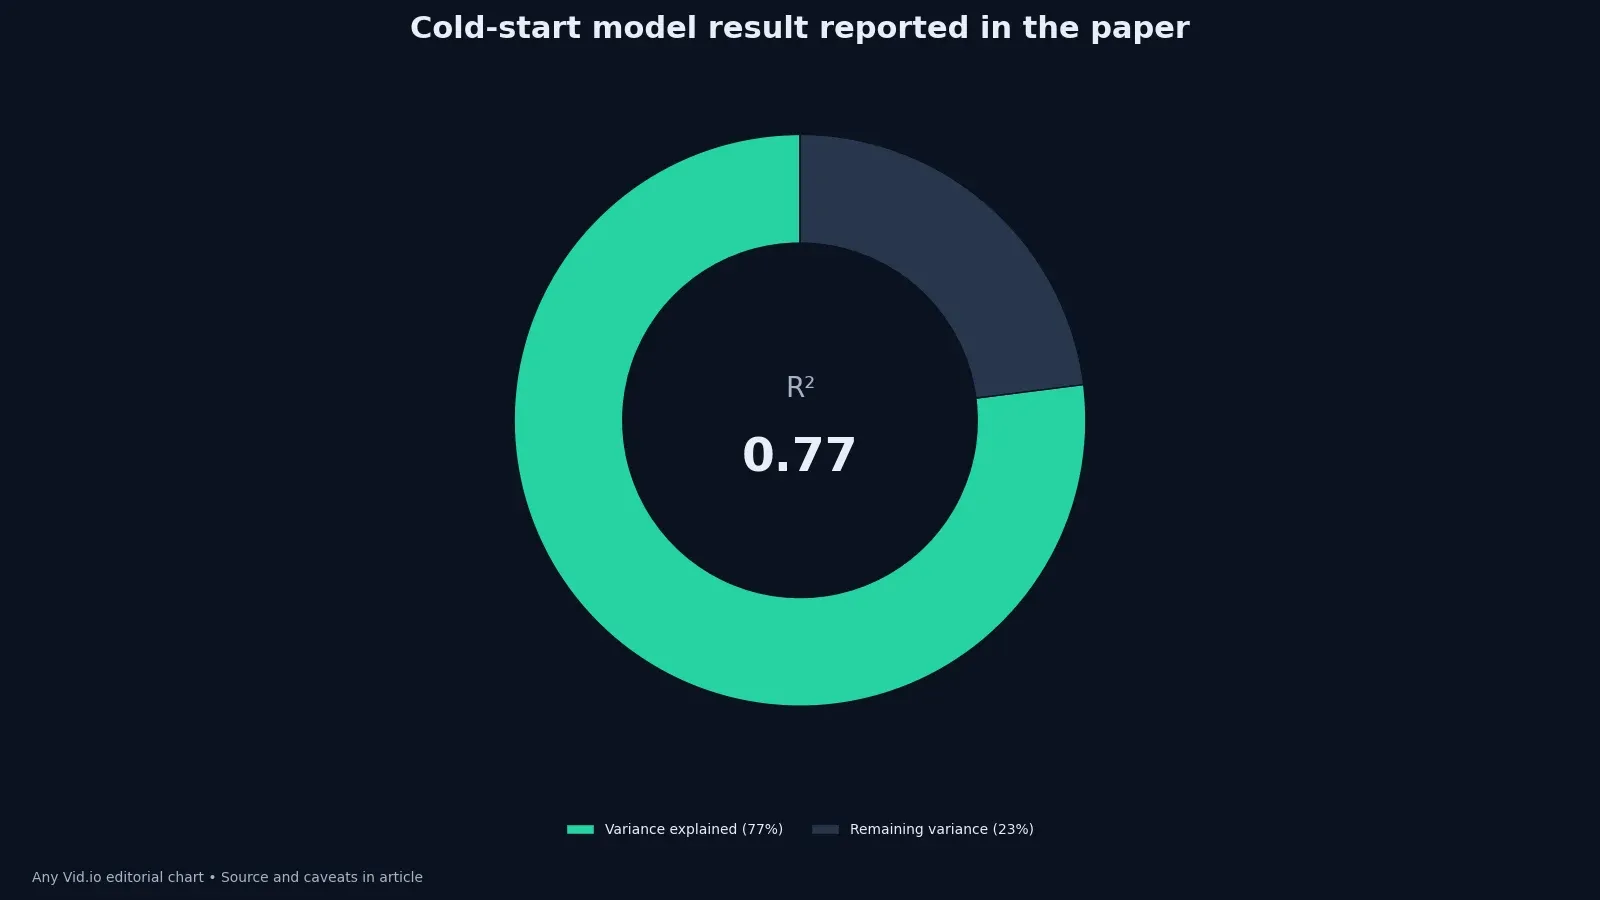
The researchers reported that engagement measures were stable over time compared with popularity, and that a cold-start model using video context, topics and channel information explained much of the variance, with R² = 0.77. This does not mean creators can predict 77% of a video’s success, nor does an old YouTube dataset describe every short-form feed today. It does demonstrate why raw views and audience holding power deserve separate columns.
Define the measures before comparing
Views count starts under a platform definition, total watch time accumulates minutes, and average percentage watched normalizes by duration. The important distinction is between what the record establishes and what an editor might infer. A published outcome can show that a particular team changed a particular system; it cannot prove that copying one visible tactic will reproduce the number. Use the evidence to choose a test, then measure that test against your own baseline.
Relative engagement in the paper calibrates engagement against video properties so unlike durations are not judged by a naive single threshold. In practice, turn that observation into a written decision before opening the camera or editor. Name the audience question, the asset that will answer it, and the signal that would justify keeping the change. This keeps a striking result from becoming a vague command to ‘do more’ and gives collaborators something concrete to challenge.
Use platform-native definitions for your own dashboard because metric thresholds and availability can change. The failure mode is easy to recognize: the headline number survives while the conditions disappear. Sample size, time window, content library, distribution surface and measurement definition all shape the result. Keep those conditions beside the metric in the project notes, especially when the source is a platform, vendor or company describing its own success.
Understand the sample and period
The 5.3-million-video scale supports population-level pattern finding within the collected public data streams. A small creator can still use the lesson without imitating the scale. Reduce the operation to one page, one video family or one campaign. Establish the current state, change one coherent bundle of decisions, and wait long enough for the relevant behavior to occur. If several variables move together, describe the result as a package rather than crediting a favorite detail.
The two-month 2016 publication window limits claims about seasonality, platform evolution and current Shorts behavior. Success should be visible in the work as well as the dashboard. A cleaner page should be easier to inspect; a stronger disclosure should be harder to miss; a better edit should answer the viewer sooner. When a metric rises but the audience experience becomes less accurate or less accessible, the experiment has found a trade-off, not an uncomplicated win.
Large samples reduce some noise but do not repair a mismatched research question. Document the unsuccessful pass too. Rejected versions show which constraints mattered and stop the team from repeating an attractive mistake six weeks later. A useful record needs the date, source material, decision owner, changed element, observation window and one sentence about uncertainty. That is enough structure for learning without building a bureaucracy.
Read R² = 0.77 correctly
R² describes variance explained by the model on the studied data under its evaluation, not a probability that any individual forecast is right. Treat the chart as a map of the published evidence, not a forecast. It compresses the reported values so patterns are easier to see, but it does not add precision the source never supplied. Thresholds such as ‘more than’ or ‘fewer than’ remain thresholds, and indexed pages, clicks, traffic and engagement must not be silently treated as the same outcome.
Context, topic and channel variables being predictive does not make them simple causal levers. Before generalizing, ask what else changed at the same time. A creator may alter cadence, subject, collaboration and presentation together; a publisher may add markup while fixing indexing; a production may combine generation with conventional editing. The honest conclusion is often that the workflow bundle worked under observed conditions, while the contribution of each part remains unknown.
Keep the remaining variance and model assumptions visible instead of presenting 0.77 as near certainty. The next test should be cheaper than the story that inspired it. Use existing footage, a limited archive, a single sponsor brief or a short run of posts. Decide in advance what would make you stop, continue or revise. Pre-committing to those choices reduces the temptation to explain every noisy result as proof that the idea was right.
Separate popularity from holding power
A promoted or externally shared video can accumulate views without unusually strong relative engagement. Finally, preserve editorial judgment. Data can expose a pattern and a case can demonstrate feasibility, but neither can decide what is responsible for your audience, sustainable for your capacity or consistent with your voice. The creator still owns that decision—and should be able to explain it without hiding behind an algorithm or a benchmark.
A useful niche tutorial can hold its intended viewers while remaining small in absolute distribution. The important distinction is between what the record establishes and what an editor might infer. A published outcome can show that a particular team changed a particular system; it cannot prove that copying one visible tactic will reproduce the number. Use the evidence to choose a test, then measure that test against your own baseline.
Choose investment decisions using both reach and depth, plus the business or community outcome the video was meant to create. In practice, turn that observation into a written decision before opening the camera or editor. Name the audience question, the asset that will answer it, and the signal that would justify keeping the change. This keeps a striking result from becoming a vague command to ‘do more’ and gives collaborators something concrete to challenge.
Build a two-axis portfolio review
Place comparable videos on a grid of reach versus duration-aware engagement. The failure mode is easy to recognize: the headline number survives while the conditions disappear. Sample size, time window, content library, distribution surface and measurement definition all shape the result. Keep those conditions beside the metric in the project notes, especially when the source is a platform, vendor or company describing its own success.
Investigate high-reach low-engagement posts for expectation mismatch and low-reach high-engagement posts for packaging or distribution problems. A small creator can still use the lesson without imitating the scale. Reduce the operation to one page, one video family or one campaign. Establish the current state, change one coherent bundle of decisions, and wait long enough for the relevant behavior to occur. If several variables move together, describe the result as a package rather than crediting a favorite detail.
Do not compare a 20-second clip and a 20-minute lesson with one universal completion target. Success should be visible in the work as well as the dashboard. A cleaner page should be easier to inspect; a stronger disclosure should be harder to miss; a better edit should answer the viewer sooner. When a metric rises but the audience experience becomes less accurate or less accessible, the experiment has found a trade-off, not an uncomplicated win.
Use reported stability carefully
Stable aggregate engagement suggests that early audience-holding signals may remain informative after popularity continues moving. Document the unsuccessful pass too. Rejected versions show which constraints mattered and stop the team from repeating an attractive mistake six weeks later. A useful record needs the date, source material, decision owner, changed element, observation window and one sentence about uncertainty. That is enough structure for learning without building a bureaucracy.
Your own small sample can still be volatile, especially when traffic sources change. Treat the chart as a map of the published evidence, not a forecast. It compresses the reported values so patterns are easier to see, but it does not add precision the source never supplied. Thresholds such as ‘more than’ or ‘fewer than’ remain thresholds, and indexed pages, clicks, traffic and engagement must not be silently treated as the same outcome.
Freeze review windows and segment sources before deciding that a pattern has stabilized. Before generalizing, ask what else changed at the same time. A creator may alter cadence, subject, collaboration and presentation together; a publisher may add markup while fixing indexing; a production may combine generation with conventional editing. The honest conclusion is often that the workflow bundle worked under observed conditions, while the contribution of each part remains unknown.
Design a fair creator review
Group by format, duration band, topic intent and traffic source where available. The next test should be cheaper than the story that inspired it. Use existing footage, a limited archive, a single sponsor brief or a short run of posts. Decide in advance what would make you stop, continue or revise. Pre-committing to those choices reduces the temptation to explain every noisy result as proof that the idea was right.
Use medians and distributions across at least several comparable videos. Finally, preserve editorial judgment. Data can expose a pattern and a case can demonstrate feasibility, but neither can decide what is responsible for your audience, sustainable for your capacity or consistent with your voice. The creator still owns that decision—and should be able to explain it without hiding behind an algorithm or a benchmark.
Add qualitative notes about viewer confusion, accessibility and whether the promised answer arrived. The important distinction is between what the record establishes and what an editor might infer. A published outcome can show that a particular team changed a particular system; it cannot prove that copying one visible tactic will reproduce the number. Use the evidence to choose a test, then measure that test against your own baseline.
Choose the next edit from evidence
Fix packaging when qualified viewers do not start, structure when starts do not become sustained attention, and targeting when the wrong viewers arrive. In practice, turn that observation into a written decision before opening the camera or editor. Name the audience question, the asset that will answer it, and the signal that would justify keeping the change. This keeps a striking result from becoming a vague command to ‘do more’ and gives collaborators something concrete to challenge.
Change one dominant variable per test so the learning remains interpretable. The failure mode is easy to recognize: the headline number survives while the conditions disappear. Sample size, time window, content library, distribution surface and measurement definition all shape the result. Keep those conditions beside the metric in the project notes, especially when the source is a platform, vendor or company describing its own success.
Preserve audience value even when a more sensational opening might increase the first metric. A small creator can still use the lesson without imitating the scale. Reduce the operation to one page, one video family or one campaign. Establish the current state, change one coherent bundle of decisions, and wait long enough for the relevant behavior to occur. If several variables move together, describe the result as a package rather than crediting a favorite detail.
Evidence table
| Metric | What it tells you | What it can hide |
|---|---|---|
| Views | How many counted starts occurred | Depth, source quality and duration |
| Total watch time | Accumulated attention | Audience size and video length |
| Average percentage watched | Share of duration viewed | Absolute minutes and intent |
| Relative engagement | Engagement calibrated to properties | Still model-dependent, not causal proof |
This evidence table for Beyond Views: Lessons From a Study of 5.3 Million YouTube Videos is deliberately compact. It preserves the unit and limitation beside each result so the number cannot wander into a slide deck as an unsupported universal benchmark. For a working analysis, add the date you accessed the source and the exact metric definition used in your own account.
Source and method
This case study relies on Wu, Rizoiu and Xie, Beyond Views: Measuring and Predicting Engagement in Online Videos. The chart redraws only values stated by that source or transparent transformations described in its caption. No private dashboard data, invented survey, simulated outcome or scraped personal information is presented as fact.
For this Creator Analytics analysis, any interest held by a platform or company reporting its own result is named; academic designs and dates remain visible. The source link lets readers inspect the original wording, while current feature or legal questions should still be checked against current primary guidance before action.
Apply the case without copying it
Choose one bounded project and write a baseline before making changes. Preserve the case’s logic—clear variables, visible evidence and honest limitations—without imitating its scale or headline outcome. Read Diagnose Short-Form Video Retention Without Chasing Benchmarks. Read Refresh Evergreen Video Pages Without Losing What Already Works. Read Film Searchable Short-Form Tutorials.
Review the Creator Analytics result with the people who make and use the content. Keep what improves clarity, trust or sustainable production; revise what merely chases the published number. Browse the AnyVid.io blog for more creator workflows. When archiving reference media, use only media you created, own, or have permission or another lawful right to save.
Frequently asked questions
Does R² = 0.77 mean 77% prediction accuracy?
No. R-squared describes the proportion of variance explained by a model under the study’s setup. It is not a classification accuracy score, a causal estimate or a guarantee for an individual video.
Why is average percentage watched not enough?
It normalizes for duration, but audiences and intents still differ. A concise answer and a long lesson have different jobs. Use duration bands, traffic sources, total watch time and qualitative viewer outcomes alongside it.
Can the 2016 findings be applied to Shorts?
Only cautiously. The paper studied YouTube videos published in 2016, before the current Shorts ecosystem. Use its measurement logic—separating popularity and engagement—rather than treating its model as current Shorts guidance.
What is a practical relative-engagement substitute?
Within your own dashboard, compare each video with the median of a genuinely similar group: same format, duration band, topic intent and observation window. Label it as your internal comparison, not the paper’s exact metric.
How many videos are enough for a creator benchmark?
There is no universal count. More comparable observations are better, but relevance matters more than a large mixed pile. Start with a clearly defined group and show the distribution and uncertainty rather than declaring a universal target.
Was this article helpful?
Tell us what worked so we can improve future content.