Model launch reels are designed to show a system at its best. A production decision needs the opposite: repeated prompts, awkward edge cases, rejected outputs, review time and a definition of usable that belongs to the actual project. Otherwise the creator selects a highlight reel and discovers the cost structure during delivery.
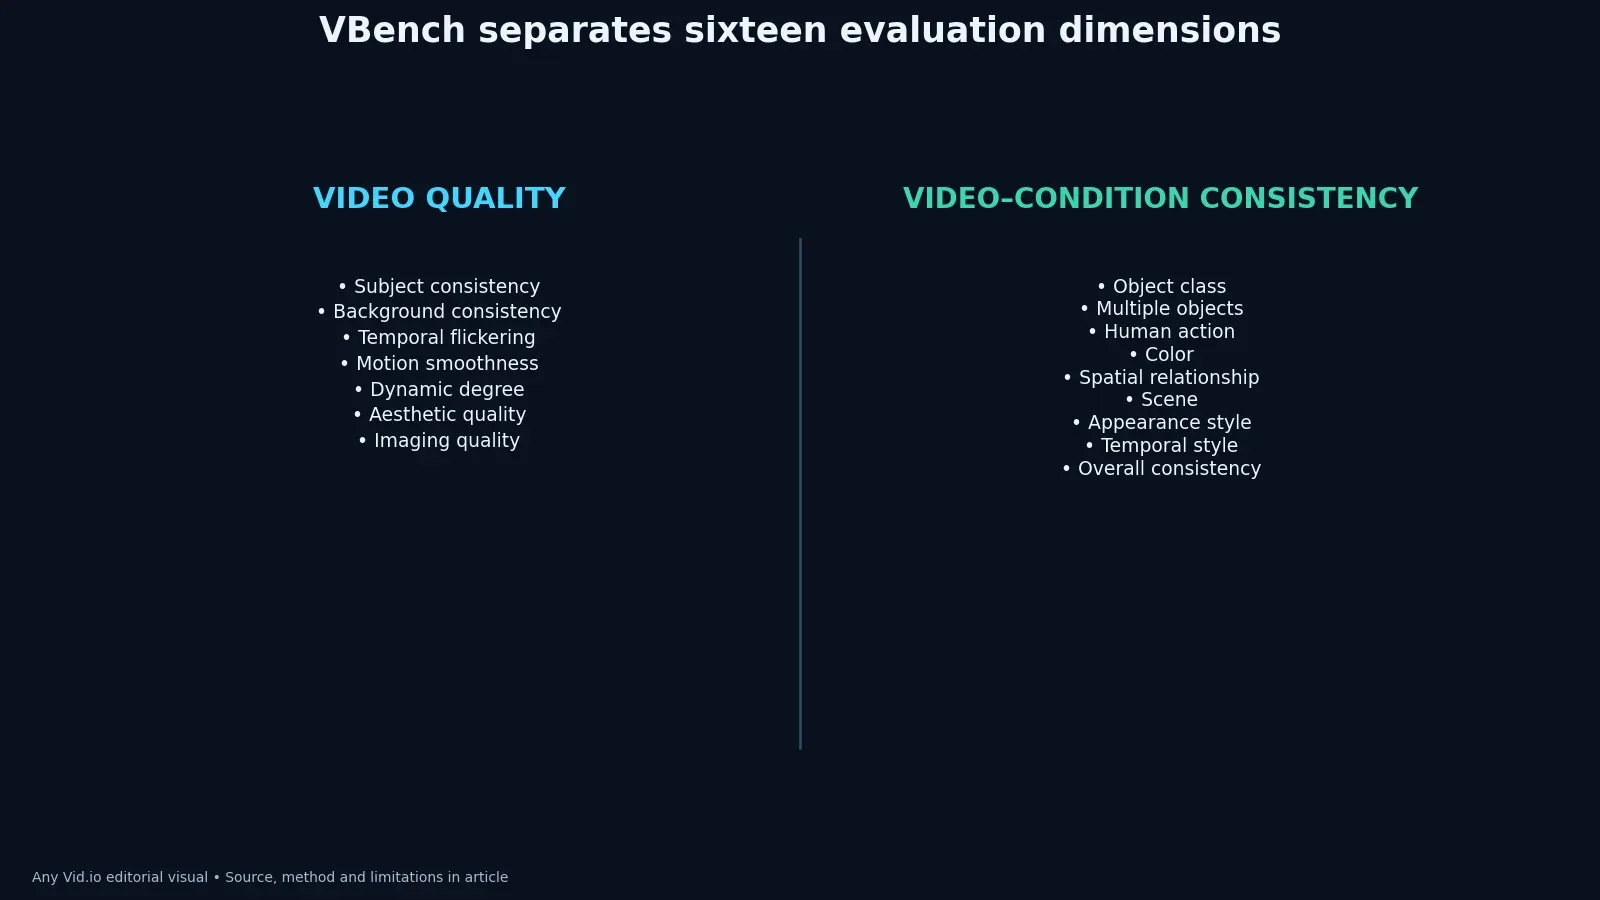
The original VBench paper proposes sixteen dimensions grouped into video quality and video-condition consistency, with roughly one hundred prompts per dimension and human preference annotations. VBench-2.0 extends the evaluation question toward intrinsic faithfulness across human fidelity, controllability, creativity, physics and commonsense. A solo creator does not need to reproduce either benchmark; the useful lesson is to stop hiding distinct failures inside one score.
Define usable before testing
Describe the shot’s job, required subject, motion, duration, edit tolerance and rights constraints before opening a model. ‘Looks good’ is too elastic for comparison. A useful review includes one sentence beginning ‘we still do not know.’ That sentence keeps observation separate from explanation. It also creates a clean opening for the next experiment instead of inviting a confident story built from incomplete evidence. For the working review, capture one screenshot or export from the relevant stage, write the exact setting or audience condition, and compare it with the planned result. Evidence that can be revisited is more reliable than a confident recollection after publication.
List automatic rejection conditions such as identity drift, unreadable product shape, unsafe motion, prohibited training references or an output that cannot be licensed for the intended use. Quality control should happen on the device and in the context where the audience encounters the work. Studio monitors, editing previews and internal terminology can hide ordinary viewing problems. Watch the delivered result, read the surrounding copy, and verify the action a real viewer can take. Ask a second person to follow the instruction without verbal coaching. Note the point where they hesitate, the assumption they make, and the proof that resolves it. Those observations often reveal a better edit than another round of generalized polishing.
Carry rejected generations into the cost model from the cost-per-usable-shot study so abundant output does not look artificially cheap. Keep the human cost in the same table as the performance signal. Minutes of filming, review burden, moderation, revisions and emotional exposure are part of the result. A tactic that produces a modest lift by doubling fragile labor may be a poor system even when the dashboard looks better. Set the review date while the decision is still emotionally neutral. Early checking rewards noise; indefinite checking encourages selective memory. A fixed window gives comparable work the same opportunity and makes exceptions visible when outside events genuinely require them.
Build a balanced prompt set
Choose a small set representing the production: people, objects, camera motion, spatial relationships, style consistency and difficult actions. Build an exit ramp before the test begins. State the safety, rights, workload or audience signal that would stop publication. Clear stopping rules help a team move quickly because they replace last-minute bargaining with decisions already connected to the brief. Write the alternative explanation beside the preferred one. If both fit the observation, the result is not yet diagnostic. The next version should separate them with a different shot, audience segment, delivery check or deliberately held-constant production choice.
Hold prompt wording, aspect ratio, duration and permitted settings constant for the primary comparison. A separate optimization round can show each model at its tuned best. The final artifact should be reusable. Save the approved language, measurement definition, visual reference and result beside the project—not only the finished file. Future work improves when the reasoning survives after the timeline and chat messages disappear. Keep raw counts where the interface permits and describe any missing fields. Rates are easier to compare, but counts expose tiny samples and sudden distribution changes. Never reconstruct a denominator from rounded percentages when the platform does not provide it.
Include ordinary connective shots, not only hero images. A model that makes one spectacular frame but fails continuity may be a poor editing partner. Do not reward a surprising result with a new myth. Check the raw observation, inspect outliers, and ask whether the metric answered the original question. The strongest conclusion may be narrower than the headline, but it will be more useful when the next project differs from this one. Turn the lesson into a checklist item that appears before the next irreversible step. Advice stored only in a retrospective is easy to admire and easy to ignore. Placement in the workflow is what converts analysis into a repeatable safeguard.
Borrow dimensions, not a leaderboard
Use VBench dimensions as a vocabulary for separate observations: subject consistency is not motion smoothness, and aesthetic quality is not prompt faithfulness. Finally, communicate the limitation where the claim appears. A footnote at the bottom cannot fully repair an exaggerated headline, and a disclaimer cannot rescue an inaccurate promise. Precise language is part of the strategy because it attracts the audience the content can genuinely serve. If collaborators are involved, agree on the metric definition and approval standard before work begins. Editors, clients and creators often use the same word for different outcomes. One written example prevents a later argument about what ‘engagement,’ ‘usable’ or ‘approved’ meant.
Select the dimensions that matter to the brief and state the omitted ones. A talking character test and an abstract texture test should not have identical weights. That sounds simple, but it changes the working question. Instead of asking whether the post was ‘good,’ the review asks which promise was made, what evidence the viewer received, and where the result departed from the plan. A useful note names the next decision; a vague verdict merely preserves the team’s mood. Review the work at normal speed before frame-by-frame inspection. Severe artifacts deserve technical attention, but a microscopic flaw that no viewer can perceive should not automatically outrank story clarity, accessibility, consent or the promised practical result.
Do not copy a published aggregate score into a buying decision without checking model version, test date, prompt method and whether the benchmark represents the shots you need. Put this in the project brief before production. The brief should identify the intended viewer, the observable behavior, the review window and the person empowered to stop the test. Pre-committing prevents a large reach number from erasing cost, confusion, weak fit or an uncomfortable audience response after the fact. Preserve the version that served as the baseline. Without it, improvement becomes a story told by the newest file. A side-by-side comparison also helps the team avoid fixing one visible weakness by quietly introducing a different problem elsewhere.
Run a blind, repeatable review
Randomize output order and hide model names during the first quality review. Familiar branding and price expectations can pull judgment toward a preferred story. A solo creator can make the method smaller without making it sloppy. Use one content family, one delivery surface and a short observation window. Change a coherent variable, capture the result, and write down what else moved. The discipline matters more than the size of the dashboard. When the outcome is mixed, resist averaging incompatible signals into a single score. State what improved, what worsened and what stayed unknown. A qualified decision is more actionable than a composite number whose weighting nobody can defend.
Generate enough repeats to reveal instability within the budget, and preserve seeds or job identifiers when the system exposes them. Success has to be visible outside analytics. The piece should answer the promised question more clearly, take less fragile labor, create a better conversation or lead to an appropriate business action. If the metric rises while trust or accuracy falls, the experiment has exposed a trade-off rather than a win. Consider the people excluded by the measurement. Silent viewers, people using captions, subscribers arriving later and clients judging deliverables may matter even when the dashboard centers immediate public reactions. Add a qualitative check for the audience the metric cannot describe.
For recurring characters, add the identity and scene controls from the character-consistency workflow rather than judging isolated portraits. Record the rejected version too. Failed openings, unusable generations and broken exports reveal constraints that a polished final cut hides. A compact log—date, source, change, owner, result and uncertainty—is enough to prevent the same attractive mistake from returning in the next production cycle. Finally, date the recommendation. Platform controls, pricing, support and technical requirements change, while the article’s underlying decision method should remain useful. A visible access date makes later verification routine instead of treating old operational details as permanent facts.
Measure labor and governance
Log generation time, queue time, retries, moderation blocks, cleanup, compositing and human review. The invoice is only one part of production cost. Before copying the tactic, ask what else happened at the same time. Topic demand, audience composition, creative quality, distribution, seasonality and collaboration can all move together. An honest review often concludes that a bundle worked under specific conditions while the contribution of each component remains uncertain. For the working review, capture one screenshot or export from the relevant stage, write the exact setting or audience condition, and compare it with the planned result. Evidence that can be revisited is more reliable than a confident recollection after publication.
Record model version, date, settings, source assets, consent and output terms. A reproducible creative decision needs a provenance trail as much as a score sheet. Make the next test cheaper than the claim that inspired it. Reuse lawful source material, limit the number of variants, and define what would make you continue, revise or stop. A small test protects time and reputation while still producing information that can improve the next brief. Ask a second person to follow the instruction without verbal coaching. Note the point where they hesitate, the assumption they make, and the proof that resolves it. Those observations often reveal a better edit than another round of generalized polishing.
Use the disclosure and rights checkpoints in the responsible AI video workflow before treating technical quality as approval to publish. Editorial judgment remains the final control. Data can reveal a pattern and documentation can reduce ambiguity, but neither decides what suits the creator’s voice, capacity or duty to the audience. Someone should be able to explain the decision in plain language without invoking a mysterious algorithm. Set the review date while the decision is still emotionally neutral. Early checking rewards noise; indefinite checking encourages selective memory. A fixed window gives comparable work the same opportunity and makes exceptions visible when outside events genuinely require them.
Make a bounded model decision
Choose a model for a defined shot family and review period, not as a universal winner. Product behavior, limits and terms can change quickly. Compare like with like. A tutorial, reaction, product demonstration and narrative scene ask different things of a viewer, so one universal target is rarely useful. Build a local comparison group with similar intent and duration, then keep the exceptions visible rather than averaging them away. Write the alternative explanation beside the preferred one. If both fit the observation, the result is not yet diagnostic. The next version should separate them with a different shot, audience segment, delivery check or deliberately held-constant production choice.
State what improved, what worsened and what remained unknown. A tool can win prompt adherence while losing continuity, labor cost or consent fit. The audience should not have to reverse-engineer the premise. Use concrete nouns, observable actions and an early indication of the payoff. That does not require frantic editing; it requires alignment between packaging and what the video actually delivers. Keep raw counts where the interface permits and describe any missing fields. Rates are easier to compare, but counts expose tiny samples and sudden distribution changes. Never reconstruct a denominator from rounded percentages when the platform does not provide it.
Schedule a retest when the model version or production need changes. Reusing the same core prompt set turns future excitement into comparable evidence. Operationally, assign this decision a home. It might live in the storyboard, rights log, offer sheet, export checklist or analytics review, but it should not depend on memory. The best systems make the responsible action easier at the moment pressure is highest. Turn the lesson into a checklist item that appears before the next irreversible step. Advice stored only in a retrospective is easy to admire and easy to ignore. Placement in the workflow is what converts analysis into a repeatable safeguard.
Working table
| Evaluation dimension | Creator-facing question | Evidence to retain |
|---|---|---|
| Subject consistency | Does the subject remain recognizable through motion? | Full clip and frame sequence, not one still |
| Motion smoothness | Does movement remain coherent at normal playback? | Normal-speed review and failure timestamp |
| Dynamic degree | Is there enough meaningful movement for the shot? | Prompt, output and intended edit use |
| Spatial relationship | Do objects stay in the requested arrangement? | Reference layout and repeated generations |
| Aesthetic quality | Does the image support the project’s visual standard? | Blind ratings plus rejection reasons |
Use this table as the working decision record for How to Evaluate AI Video Models With a Reproducible Test Set, not as decorative authority. Replace illustrative entries with dated observations from the real project, keep definitions beside the result, and preserve the source whenever a published fact changes the decision. The useful row is the one that tells the next editor what to verify.
Put the method to work
Run the first test with a modest prompt set and a brutally clear usable-shot definition. Preserve every rejection and its reason. The winning model is the one that fits this production under these conditions—not the name attached to the prettiest launch reel.
The AnyVid.io blog includes related AI cost, consistency and disclosure guides. Use authorized inputs, document model versions and obtain consent wherever identifiable people or voices are involved.
Frequently asked questions
Does VBench identify the best AI video model for every creator?
No. VBench offers a structured benchmark across multiple dimensions. A creator’s best choice depends on shot requirements, model version, settings, cost, rights, review labor and acceptable failure modes. Use benchmark results as evidence, not a universal purchasing verdict.
Why use fixed prompts for model comparison?
Fixed prompts reduce one source of variation, so differences are easier to attribute to the model and settings. You can run a second tuned comparison later, but changing prompts, duration and guidance simultaneously makes the first result difficult to interpret.
How many generations should I test?
Use enough repeats to expose instability within a budget you can document. There is no universal minimum for a small production test. State the sample and avoid turning a handful of outputs into a broad quality claim.
Should I combine every dimension into one score?
Only if the weights are explicit and defensible for the project. Separate results are usually more informative: a composite can hide a severe identity, physics or prompt-adherence failure behind attractive imagery.
Can I test models with a real person’s face or voice?
Only with appropriate consent, rights and safeguards for the intended use. Prefer controlled, authorized source material, document permissions and avoid assuming that technical access grants the right to imitate an identifiable person.
Was this article helpful?
Tell us what worked so we can improve future content.